Light is right
Light is right
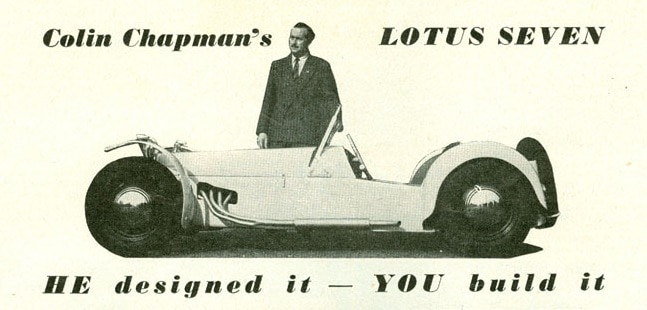
Do you know Colin Chapman? If you don’t take an interest in automotive history, he probably means nothing to you. Even if you’ve already come across his creations on the street or in film / TV.
This handsome mustached man created the sports-car brand Lotus, with a credo: “Light is right”. 7, Esprit, Elan, Elise, this maxim found its way into the design of his vehicles: light cars, far less powerful than their rivals but much more effective, making up for their lack of power with agility.
Why am I talking to you about Lotus? You’ll make the connection.
Barbara & Roger
Within the space of a week, 2 particular announcements in generative AI that take opposite approaches:
💪 [the muscle] Abu Dhabi’s technology university (Technology Innovation Institute) made official the release of Falcon 180B, an LLM containing more parameters than GPT-3.5 (+5B), with a license that allows commercialization (restrictive, though), which makes it the most powerful “open source” LLM of the moment. The model was trained on 3.5T tokens, that is 2,600,000,000,000 words (that’s a lot). A monster that required 7 million hours of training (certainly costing several tens of millions of dollars — about $50M, AWS is happy) and that will be fairly expensive to use given its size.
😏 [the clever one] Microsoft Research releases phi-1.5 “open source”, a small model. Why small? You’ll be able to compare it with what’s above. 1.3B parameters, trained on 7 billion tokens. The model is rather specialized in computer-code completion but also comes with reasoning abilities. This model scores 50.6% on Human Eval(*), which puts it not very far from GPT-4 (67%) or wizardCoder (57%). Which is pretty incredible given the size of the model and the size of the training set. On the cost side, we must be around a few tens of thousands of dollars for the training and the generation of the dataset, not counting of course the human costs of R&D and of work on the dataset. FUN FACT: the training must have cost less than generating the dataset.
How did they do it? Instead of training the model with data of variable quality, they worked from code available on Github and used GPT-4 and GPT-3.5 to build a synthetic dataset of “quality” data.
To simplify greatly, one LLM produced the training data of another LLM (or helped produce it).
Why is it interesting? Comparing Falcon and Phil doesn’t really make sense, because you can’t expect the same results from Phil on non-specialized work, but it opens a new path, that of the availability of small models, specialized, cheap to create as well as to use, and easily fine-tunable on your own data.
This approach will (I think) make it possible, at low cost, to explore new paths and new use cases.
I actually think this is the future of generative AI, the massive use of small models, fine-tuned on proprietary datasets, costing only a few thousand euros to train and cheap to use. (And that is, moreover, the intuition we want to explore with Coddity).
“Light is right” Colin
(*) “Human Eval” is an approach for evaluating the performance of LLMs, created by OpenAI, which makes it possible to compare models with each other.
DISCLAIMER Why I put open source in "" => a truly open source LLM would make available to the community its code, the way it was built, and its dataset. Generally, open-source LLMs are rather black boxes available on Hugging Face with licenses that let you use them on your projects, with usage or commercial restrictions.